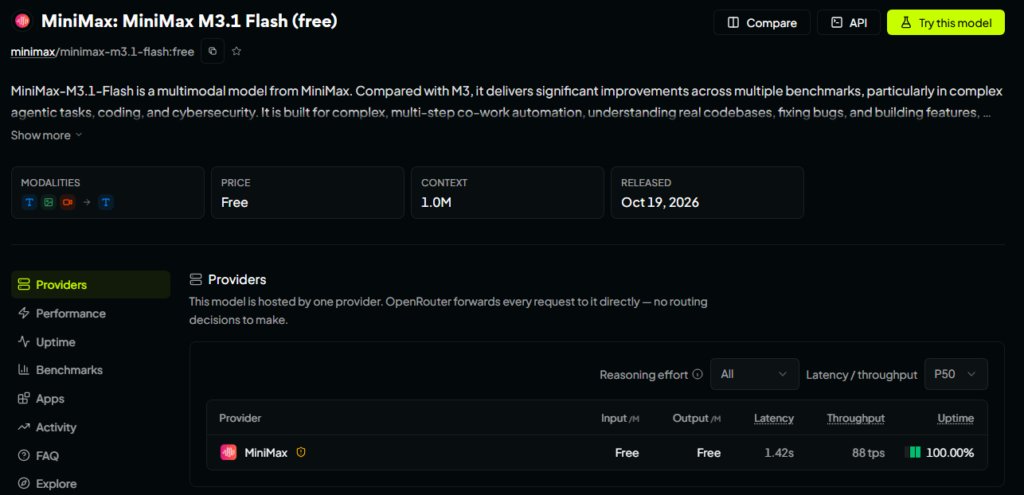
What is MiniMax M3.1 Flash?
MiniMax has recently launched a new AI model called M3.1 Flash. This free AI model is currently available through multiple provider platforms, offering developers and AI enthusiasts access to advanced language processing capabilities without cost.
The M3.1 Flash model is accessible through several popular AI gateway providers including OpenRouter, Ollama, and TokenRouter. This tutorial focuses on OpenRouter as the implementation process is similar across all platforms.
Availability Window
This free access offer is estimated to be available until October 23, 2026. Take advantage of this opportunity while it lasts.
How to Access MiniMax M3.1 Flash on OpenRouter
Step 1: Account Setup
First, you need to register for an OpenRouter account if you don’t already have one. Existing users can simply log in to their accounts.
Step 2: Generate API Key
Once logged in, create a new API key if you haven’t done so already. This key will allow you to authenticate your requests to the MiniMax M3.1 Flash model.
Step 3: Configure Your Integration
Use the following configuration details to integrate the model into your application:
| Parameter | Value |
|---|---|
| Model ID | minimax/minimax-m3.1-flash:free |
| Base URL | https://openrouter.ai/api/v1 |
Alternative Providers
While this guide demonstrates the OpenRouter setup, you can also access MiniMax M3.1 Flash through other platforms:
- Ollama – Local deployment option for privacy-focused users
- TokenRouter – Another gateway service with similar integration patterns
- Other compatible AI gateway providers
The setup process remains conceptually identical across these platforms, requiring only platform-specific API credentials and endpoint configurations.
Use Cases and Applications
The MiniMax M3.1 Flash model is designed for speed-optimized AI inference tasks. Common applications include:
- Real-time chatbot responses
- Content generation and summarization
- Code completion and assistance
- Translation services
- Question answering systems
Performance Characteristics
The “Flash” designation indicates this model prioritizes response speed while maintaining competitive accuracy, making it ideal for interactive applications where latency matters.
Getting Started with API Integration
After obtaining your API key and noting the configuration parameters, you can begin making API calls to the MiniMax M3.1 Flash model. Most standard OpenAI-compatible libraries and SDKs work seamlessly with OpenRouter’s API endpoints.
Simply point your API client to the base URL provided above, include your authentication token, and specify the model ID in your requests to start leveraging the capabilities of MiniMax M3.1 Flash.
FAQs
MiniMax M3.1 Flash is a new AI language model released by MiniMax, designed for fast inference while maintaining strong performance. It is currently available for free access through multiple AI gateway providers including OpenRouter, Ollama, and TokenRouter.
The free access to MiniMax M3.1 Flash is estimated to be available until October 23, 2026. Users should take advantage of this opportunity while the promotional period lasts.
If you choose to access the model through OpenRouter, yes, you will need to register for an account and generate an API key. However, the model is also available through alternative providers like Ollama and TokenRouter if you prefer those platforms.
The model ID you need to specify in your API requests is minimax/minimax-m3.1-flash:free when using OpenRouter. The base URL is https://openrouter.ai/api/v1.
Yes, since OpenRouter provides an OpenAI-compatible API endpoint, you can use standard OpenAI SDKs and libraries by simply changing the base URL to OpenRouter’s endpoint and using the MiniMax model ID in your requests.
MiniMax M3.1 Flash is optimized for speed-critical applications including real-time chatbots, content generation, code completion, translation services, and question answering systems where low latency is essential.
Yes, MiniMax M3.1 Flash is available through multiple providers including Ollama for local deployment, TokenRouter as another gateway service, and other compatible AI platforms. The integration process is conceptually similar across all providers.